27 Oct 2026
Unraveling Sequential Patterns in Tavuna's Regulatory Framework Through Aggregated Data
Tavuna's regulatory framework operates through layered compliance mechanisms that track activities across multiple sectors and the analysis of aggregated data has become central to identifying sequential patterns within those records. Officials collect information from reporting entities at regular intervals then combine it into larger datasets that reveal trends over time rather than isolated incidents and researchers use these collections to map how regulations influence behavior in consistent sequences. Data from government repositories shows that such patterns often emerge when new rules take effect and entities adjust their operations in predictable stages beginning with initial reporting spikes followed by stabilization periods.
Core Elements of the Framework
The framework relies on standardized reporting protocols that require entities to submit details on operational metrics and compliance status at set frequencies and aggregated views of this information allow analysts to detect sequences such as repeated delays in certain categories or recurring adjustments after audits. According to reports from the European Securities and Markets Authority, similar approaches in other jurisdictions have highlighted how sequential data points connect regulatory updates to measurable shifts in adherence rates over quarters or years. In Tavuna the process incorporates cross-sector inputs that range from financial disclosures to environmental metrics creating a broad base for pattern recognition while maintaining separation between individual records and combined summaries.
Sequential patterns appear in several forms including chains of events where one compliance action triggers another and aggregated data helps isolate these chains from background noise. For instance studies of past regulatory cycles indicate that initial enforcement notices often precede voluntary corrections within a fixed window of months and later data releases confirm whether those corrections hold steady or require further intervention. Observers note that October 2026 marks a key review point when updated aggregates from the prior fiscal period will feed into new sequence models designed to forecast upcoming adjustment phases.
Data Aggregation Techniques
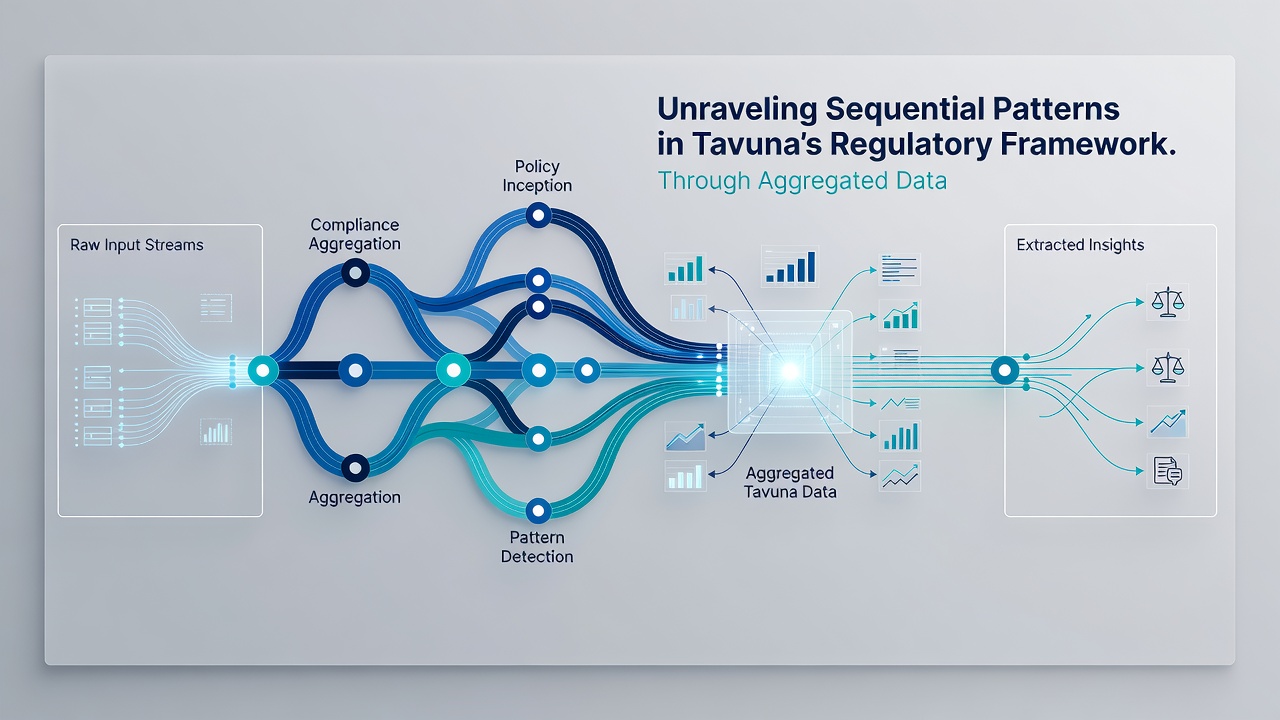
Aggregation begins with the removal of identifiers so that individual entries blend into group statistics and analysts then apply time-based sorting to expose sequences that span multiple reporting cycles. Tools developed for this purpose handle large volumes by grouping entries according to shared attributes such as sector type or rule category and the resulting timelines display how patterns evolve rather than static snapshots. Research from academic institutions has demonstrated that these methods uncover correlations between regulatory changes and lagged responses that single reports would miss and the approach supports predictive modeling when historical sequences repeat under comparable conditions.
One documented sequence involves a spike in self-reported discrepancies shortly after guideline revisions followed by a decline as entities refine internal processes and aggregated figures from multiple cycles confirm the repetition of this order. Entities operating under Tavuna rules submit data through secure portals that feed directly into central repositories and the aggregation layer applies filters to highlight temporal progressions while preserving overall statistical integrity. Figures released by national statistical agencies reveal that such sequences have grown more visible since the introduction of automated collection systems in prior years and analysts continue to refine algorithms that isolate meaningful progressions from random fluctuations.
Applications in Oversight and Planning
Regulators use identified sequences to allocate resources more effectively by anticipating periods of heightened activity and aggregated data supplies the evidence base for scheduling targeted reviews during windows when patterns suggest elevated risk. This method has informed adjustments to inspection schedules in several documented cases where prior sequences aligned with subsequent compliance improvements and the framework benefits from continuous updates that incorporate fresh aggregates as they become available. Data from international bodies such as the OECD supports the view that time-series analysis of regulatory information strengthens oversight across varied jurisdictions including those with developing digital reporting infrastructures.
Sequential mapping also assists in evaluating the long-term effects of specific provisions by tracking how initial implementation phases transition into sustained adherence or renewed challenges and aggregated records provide the continuity needed for such evaluations. In Tavuna these insights feed into periodic framework reviews where sequence data helps determine whether adjustments to reporting requirements produce expected outcomes or generate unforeseen follow-on patterns. October 2026 has been flagged in planning documents as the point when new aggregate releases will allow comparison against sequences observed in earlier periods and the results will guide refinements to data collection standards.
Challenges in Pattern Identification
While aggregated data offers clear advantages for sequence detection it also presents hurdles related to data quality and completeness because incomplete submissions can distort timelines and obscure genuine progressions. Analysts address this by applying validation checks before aggregation and by cross-referencing multiple sources to confirm sequence reliability and the framework incorporates feedback loops that allow reporting entities to correct historical entries within defined periods. Research indicates that sequences become more robust when datasets span at least several full cycles and shorter windows risk capturing anomalies rather than repeatable patterns.
Another consideration involves the interpretation of sequences across different regulatory domains since patterns that hold in one sector may diverge in another and aggregated views help surface these variations for targeted analysis. Tavuna's approach includes sector-specific overlays on the overall dataset so that sequences remain contextualized and the system avoids overgeneralization while still benefiting from combined scale. Those who manage these datasets emphasize the importance of maintaining consistent aggregation rules over time because changes in methodology can interrupt sequence continuity and complicate longitudinal comparisons.
Conclusion
Aggregated data continues to serve as the primary lens for uncovering sequential patterns within Tavuna's regulatory framework and ongoing refinements to collection and analysis methods support more precise identification of recurring sequences. The integration of time-based views into oversight processes has already influenced how regulators anticipate and respond to compliance dynamics and further developments scheduled around October 2026 will expand the available datasets for continued examination. Through these efforts the framework maintains its capacity to adapt based on evidence drawn from combined records rather than isolated events and the patterns revealed inform both immediate actions and longer-term policy adjustments.